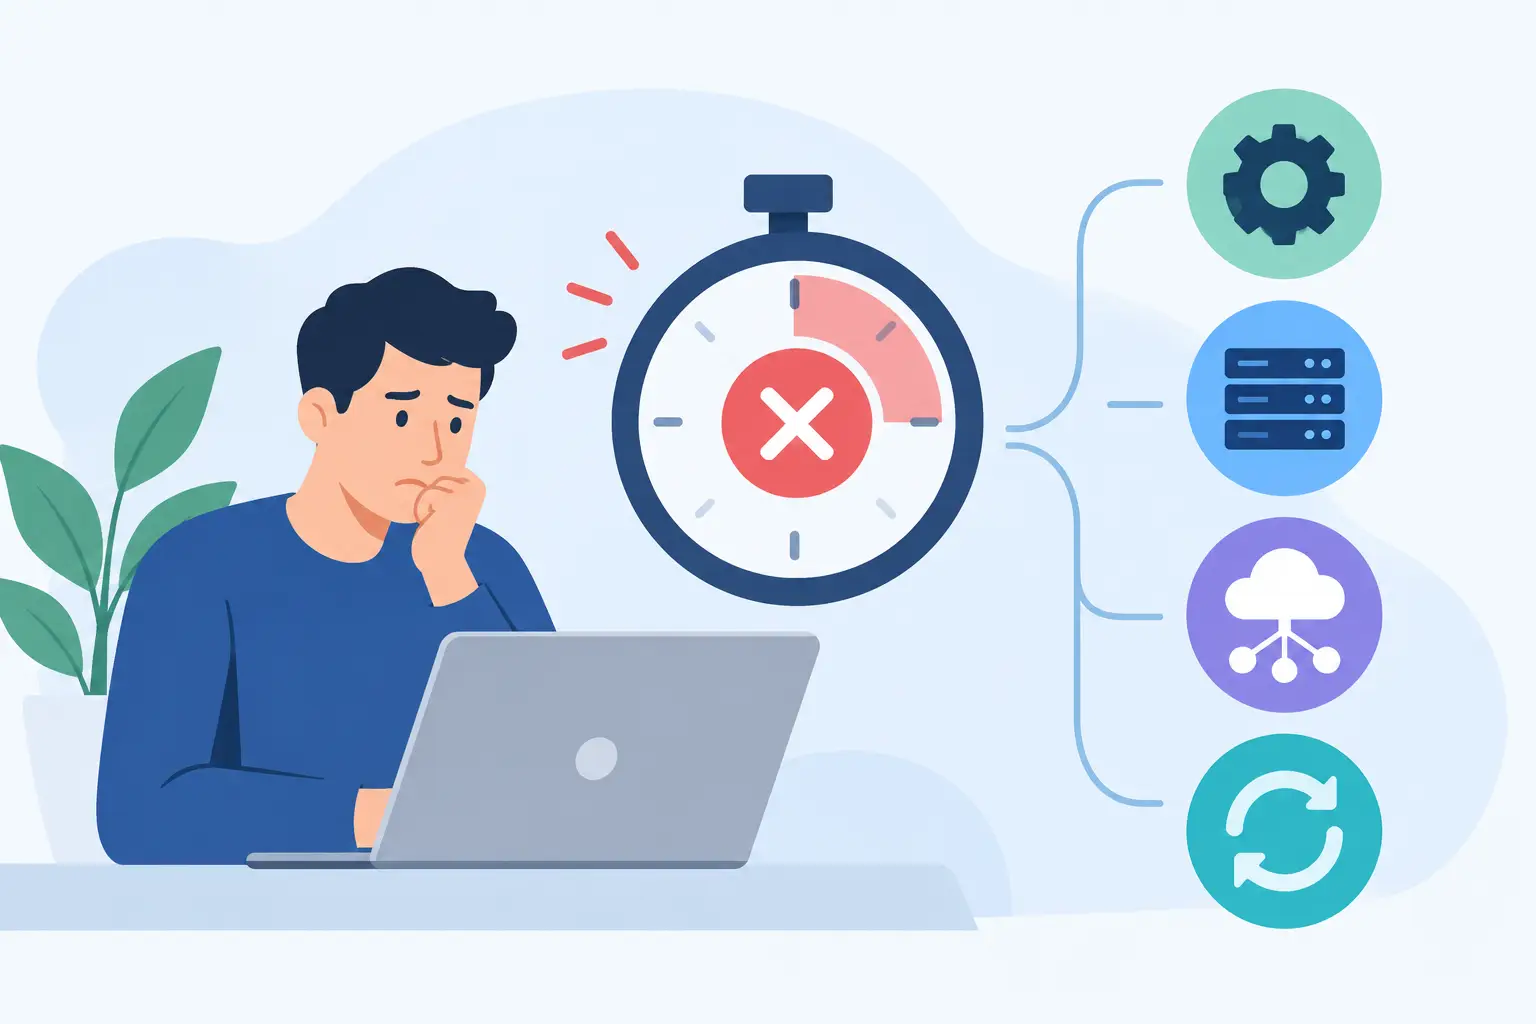
A timeout is rarely just a slow request. It is a contract expiring somewhere between a user action and a dependency response. The challenge with application timeout causes is that several layers can enforce that contract at once: browsers, load balancers, API gateways, service clients, application runtimes, databases, and third-party platforms.
When teams respond by simply increasing a timeout value, they may reduce visible errors while making capacity problems, thread exhaustion, and poor user experiences worse. The more useful approach is to identify which layer ended the request, why it waited, and whether the work should have been synchronous in the first place.
What an application timeout actually means
A timeout occurs when a component stops waiting for an operation to complete within its configured deadline. The component may cancel the request, close a connection, return an error, or leave work running in the background depending on the protocol and implementation.
That distinction matters. A client-side timeout can tell the user that an operation failed even while the server continues processing it. If the user retries a payment, provisioning task, or write operation without an idempotency strategy, the result can be duplicate work rather than a clean recovery.
Timeouts also come in several forms. A connection timeout means a client could not establish a connection quickly enough. A read or response timeout means the connection was made but no data arrived before the deadline. An idle timeout usually means an intermediary closed a connection that appeared inactive. A total request deadline places a ceiling on the entire operation, including retries and downstream calls.
The most common application timeout causes
Most incidents fall into a handful of patterns, but the visible symptom can be misleading. A 504 response from a gateway, for example, does not automatically prove the application server is slow. The gateway may be unable to reach it, the network path may be impaired, or a downstream service may be holding the request open.
Slow or blocked database work
Database latency is among the most frequent causes because applications often wait for a query before producing any response. Missing indexes, inefficient joins, large scans, lock contention, overloaded replicas, and exhausted connection pools can all turn a normally fast endpoint into a timeout candidate.
Locking deserves special attention. A query may be fast in isolation but wait behind a long-running transaction. Application performance monitoring can show an endpoint’s duration, but database-level telemetry is needed to reveal whether time was spent executing, queued for a connection, or blocked on a lock.
Downstream service latency and failure
Modern applications commonly assemble one response from multiple internal APIs, SaaS platforms, identity providers, caches, and payment services. One slow dependency can consume the request budget for every caller upstream.
This risk compounds when services use retries without limits. If Service A retries calls to Service B while Service B retries calls to Service C, a brief slowdown can create a surge of duplicate traffic. The system spends more time waiting and less time completing useful work. What began as a localized dependency issue becomes a broad timeout event.
Connection pool and worker exhaustion
An application can appear healthy at low traffic and fail under moderate load because all available workers, threads, database connections, or HTTP connections are occupied. New requests then wait in a queue until their deadline expires.
This is why average latency alone is not enough. Monitor queue depth, active versus idle connections, pool wait time, request concurrency, CPU utilization, memory pressure, and p95 or p99 latency. A rising pool wait time often points to saturation before users see widespread timeout errors.
Network, DNS, and TLS problems
Not every delay belongs to application code. DNS lookup failures, stale records, packet loss, asymmetric routing, firewall rules, certificate negotiation issues, and misconfigured proxies can prevent a request from reaching its destination or returning cleanly.
These failures can be intermittent, which makes them especially frustrating. A single successful curl command from a developer workstation does not validate the network path from a production container, serverless function, or private subnet. Test from the workload’s actual runtime environment and capture timing for DNS, connection, TLS handshake, first byte, and full response.
Misaligned timeout settings
A request may pass through several components, each with a different timeout. Consider a browser that waits 60 seconds, a CDN that waits 30, an API gateway that waits 29, and an application client that waits 10. The user may see a gateway error at 29 seconds even though the application is still waiting on a dependency configured for 45 seconds.
Misalignment also creates wasted work. If an upstream gateway has already abandoned a request, downstream systems should ideally receive cancellation signals or stop work when they can. Otherwise, the platform keeps spending compute and connections on results that no client will receive.
Large payloads and expensive synchronous tasks
Endpoints that generate exports, resize media, process large files, render reports, or call many services in sequence are poor fits for short synchronous request windows. The immediate fix may be a longer timeout, but that can tie up workers and degrade unrelated traffic.
For long-running work, return an accepted status with a job identifier, process the task asynchronously, and expose status or completion notifications. This changes the interaction model, but it protects the request path and gives users a clearer outcome than a spinning page followed by an error.
How to diagnose timeout causes without guessing
Start with the exact failure boundary. Determine whether the timeout was emitted by the browser, mobile app, CDN, load balancer, gateway, service mesh, application framework, HTTP client, database driver, or database. Error text, status codes, proxy logs, and client telemetry can narrow this down quickly.
Next, correlate one request across layers. A request ID or distributed trace should show when the request entered the system, where time was spent, which dependency call was slow, and whether retries occurred. Without correlation, teams often compare unrelated log lines and chase the component that reported the error instead of the component that created the delay.
Use a time budget for the request. If an API has a 2-second user-facing target, it cannot safely give three downstream calls 2 seconds each. Reserve time for connection setup, serialization, internal processing, and error handling. Then assign smaller, explicit deadlines to dependencies based on their expected latency and business importance.
A practical investigation usually answers these questions:
- Did the request fail while connecting, waiting for a response, or transferring data?
- Is the issue isolated to one endpoint, deployment, availability zone, tenant, or dependency?
- Did latency rise before errors, and did retries amplify the traffic?
- Were workers, threads, sockets, or database connections queued or exhausted?
- Did a recent configuration, schema, traffic, or infrastructure change alter the request path?
Load testing can validate the hypothesis, but reproduce production conditions as closely as possible. Test realistic payload sizes, connection reuse, cache state, concurrency, and dependency behavior. A test that hits only a warmed-up endpoint on a local network will not reveal an overloaded connection pool or a cross-region DNS problem.
Fixes that improve reliability instead of hiding symptoms
The right remediation depends on the bottleneck. Slow queries may need indexes, query rewrites, smaller result sets, or transaction changes. Connection exhaustion may require pool tuning, leak detection, reduced concurrency, or more database capacity. A failing third-party API may call for cached data, a fallback experience, or a circuit breaker that fails quickly when the dependency is unhealthy.
Timeout values should reflect the operation, not become a blanket setting. A lightweight profile lookup and a report-generation endpoint should not share the same deadline. Set connection, read, and total deadlines deliberately, then make the caller’s deadline shorter than the deadline of the component it is waiting on. This leaves time for cleanup and a controlled response.
Retries need equal care. Retry only failures likely to be transient, use exponential backoff with jitter, cap attempts, and respect the overall request budget. For writes, use idempotency keys or another deduplication method before allowing automated retries. Retrying a request that may already have succeeded is a product and data-integrity decision, not merely an infrastructure setting.
Circuit breakers, bulkheads, queues, and rate limits each address a different failure mode. Circuit breakers stop repeated calls to an unhealthy dependency. Bulkheads prevent one dependency or tenant from consuming all shared resources. Queues move suitable work off the synchronous path. Rate limits protect the system when demand exceeds safe capacity. None replaces performance work, but together they keep a localized slowdown from becoming a platform-wide outage.
Build timeout-aware applications
Timeouts should be observable design signals, not occasional errors buried in logs. Track timeout rate by endpoint and dependency, alert on latency trends before error thresholds are crossed, and review timeout configurations whenever the request path changes. Include cancellation handling and idempotency in API design rather than treating them as emergency additions.
The goal is not to eliminate every timeout. A well-chosen timeout protects users and shared infrastructure from waiting indefinitely. The real win comes when a timeout tells your team exactly where to act, while the rest of the application continues serving useful work.