Release control is not the same as deployment
A production deployment should not have to mean exposing a new capability to every customer at once. Yet many teams still treat those events as inseparable. That approach turns routine releases into high-stakes moments, especially when a change touches payments, authentication, data migration, or a heavily used workflow.
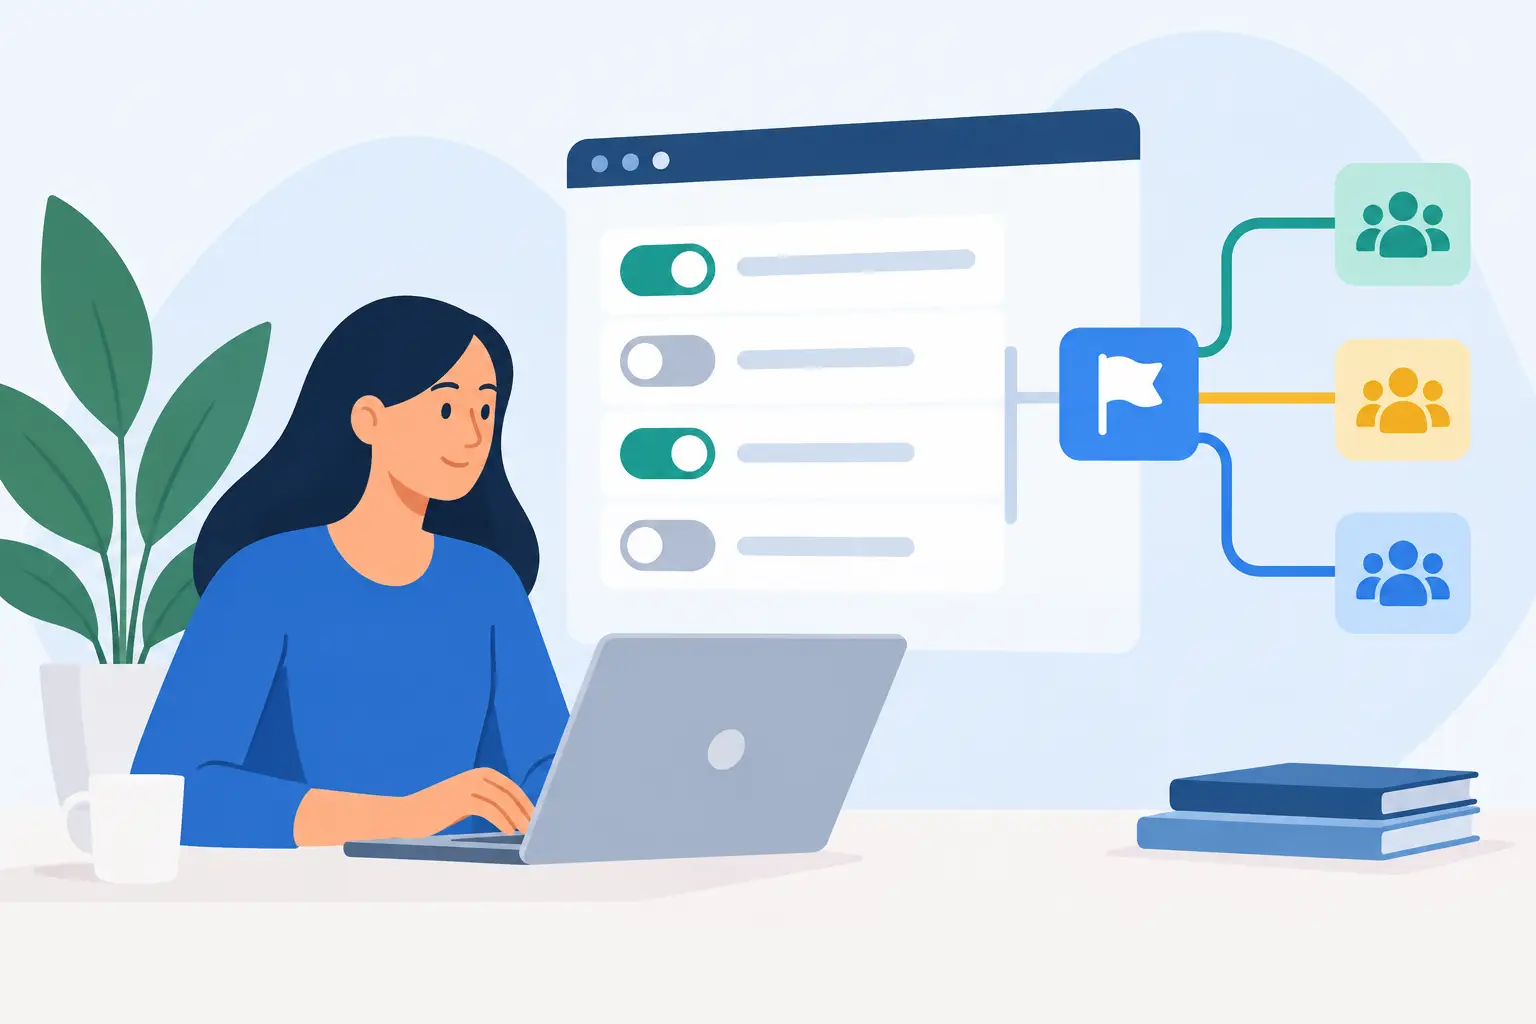
When you set up feature flags, you separate code delivery from feature exposure. The application can contain a finished capability while a flag determines who can see it, when it is enabled, and how quickly it can be disabled. Used well, flags reduce release risk and give product, engineering, and operations teams better control over change.
Used carelessly, they create conditional logic that nobody owns. The goal is not to put every decision behind a switch. It is to build a small, disciplined release-control system that supports safe experimentation and fast recovery.
Start with a flag taxonomy
Before choosing a platform or adding an SDK, define the kinds of flags your team will allow. Different flags have different lifecycles, owners, and operational risks. Treating them all the same is a common reason a clean codebase becomes crowded with permanent conditions.
A release flag temporarily hides a completed feature while it is validated in production. For example, a new checkout interface may ship disabled, then be enabled for internal users before a broader rollout. Release flags should have a planned removal date because the feature will eventually become either the default behavior or be removed.
An operational flag controls system behavior during an incident or periods of elevated load. A team might use one to disable expensive report generation, bypass a nonessential third-party enrichment call, or turn off image processing. These flags need stricter access controls because changing them can affect availability, cost, or data quality.
An experiment flag supports controlled comparisons between variations. It may assign users to a new onboarding flow or pricing-page design. Experiment flags require stable assignment rules and analytics that distinguish exposure from conversion. Without both, the team may draw conclusions from incomplete data.
Permission flags expose capabilities to specific account tiers, regions, or customer groups. These often live longer than release flags, but they should still be modeled carefully. If a capability is a durable entitlement, a formal authorization or subscription system may be a better fit than an endlessly reused feature flag.
Choose the evaluation point deliberately
A flag can be evaluated on the server, in the client, at the edge, or through a hybrid approach. The right choice depends on what is being controlled and what information must remain private.
Server-side evaluation is usually the safest default for sensitive logic. The backend can use trusted attributes, such as account plan or internal-user status, without sending targeting rules to the browser. It also prevents a client from simply modifying a local response to access an unreleased capability.
Client-side evaluation can work well for low-risk interface changes, such as a redesigned navigation element. It can reduce round trips and make front-end experiments easier to manage. The trade-off is visibility: any flag definitions and values sent to the browser should be assumed discoverable. Never use a client-side flag as the only control for an administrative action, premium API endpoint, or security boundary.
For systems with strict latency requirements, edge evaluation can be useful. It enables regional or user-specific decisions close to the request while avoiding a centralized lookup on every page load. That benefit comes with added operational complexity, including cache consistency, propagation delays, and observability across locations.
How to set up feature flags with safe defaults
A reliable implementation begins with the behavior that applies when the flag service is unavailable. This is not an edge case. Network failures, expired credentials, SDK initialization errors, and configuration outages all happen. Every flag needs an explicit fallback value in application code.
For a new, unproven feature, the fallback should usually be off. For an operational safeguard that disables a harmful dependency, the desired fallback may be on. The important point is that the default reflects the safer business and technical outcome, not whichever boolean value feels intuitive.
Keep flag checks close to the decision they govern. A UI component can check whether to render a new button, while the API must independently enforce whether the underlying operation is allowed. Do not rely on a hidden client control as protection for a server action.
Also avoid scattering the same raw flag key throughout the codebase. Wrap flags in a small domain-oriented interface, such as `canUseNewCheckout(account)` or `shouldGeneratePreview(request)`. This makes intent clearer, centralizes fallback behavior, and makes cleanup less error-prone when the flag is retired.
Design targeting rules that are easy to reason about
Targeting is where feature flags become more than on-off switches. Start with broad, understandable cohorts: employees, test accounts, a small percentage of production traffic, or a designated customer group. Avoid combining many loosely defined attributes in one rule unless there is a clear operational need.
Progressive delivery is a practical rollout pattern. Enable a release for internal users first, then a small percentage of customers, then larger cohorts while monitoring errors, latency, support tickets, and key business metrics. A percentage rollout should use a stable identifier, such as an account ID or user ID, so a person does not randomly switch experiences between requests.
Account-level targeting is often better than user-level targeting for collaborative products. If one person at a company receives a new workflow while teammates do not, support and training become harder. On the other hand, user-level targeting is useful for individual experiments where independent assignment is part of the design.
Be cautious with geography-based rules. They can help with regional compliance or staged infrastructure expansion, but location data may be inaccurate, and users can move between regions. For critical requirements, enforce the rule in the system of record rather than relying only on a presentation-layer flag.
Build observability around flag changes
A flag rollout without telemetry is just a controlled guess. Before exposing a feature, decide which signals would tell you it is working and which would trigger a rollback. Technical signals may include error rates, latency percentiles, queue depth, resource consumption, and dependency failures. Product signals may include completion rates, abandonment, or support volume.
Log the evaluated flag state with relevant requests and errors, while avoiding unnecessary personal data. When an incident begins, engineers need to answer a basic question quickly: did the affected requests receive the new behavior? A trace or structured log field that captures a flag version or variation can cut investigation time significantly.
Audit logs matter as well. Teams should know who changed a flag, what changed, and when. This is especially valuable for operational flags and production experiments. If a change requires approval in your environment, make that workflow part of the flag platform or deployment process rather than relying on a chat message.
Prevent feature flags from becoming permanent debt
Feature flags are temporary complexity, even when they are valuable complexity. Every active flag increases the number of possible application states. Two independent flags create four paths; five create 32. Not every combination will be tested, and some combinations will be invalid.
Give each flag an owner, a purpose, a creation date, and an expiration or review date. A simple naming convention helps, such as a domain prefix followed by a concise behavior name. Names like `checkout-new-tax-calculation` are far more useful than `flag_27` when an engineer is diagnosing a production issue.
Set a removal plan before the flag is created. Once a rollout succeeds, remove the old path, delete the flag configuration, update tests, and retire dashboards or alerts that exist only for that rollout. If an experiment loses, remove the variant with the same discipline. Keeping both paths “just in case” converts a short-term safety mechanism into long-term maintenance cost.
Automated checks can reinforce this practice. Your build pipeline can warn about expired flags, fail when a flag lacks an owner, or generate a report of keys that exist in code but not in the configuration service. These controls are modest investments compared with debugging behavior controlled by a forgotten switch two years later.
Treat flags as part of your delivery architecture
The strongest feature-flag programs are not defined by a particular vendor. They are defined by clear ownership, secure evaluation, measured rollouts, and disciplined removal. A lightweight internal solution may be enough for a small application with a few release controls. A larger organization may need centralized management, audit trails, SDK support across languages, and advanced targeting.
Either way, begin with one high-value use case: a risky release that would otherwise require a late-night deployment window or a full rollback. Set clear defaults, instrument the rollout, and schedule the cleanup before enabling the feature. That habit turns feature flags from scattered booleans into a dependable part of how your team ships change.